In risk assessment, delays do not always result from missing studies. A missing unit, inconsistent substance name or vague method description can make evidence difficult to use. In regulated sectors, these details determine whether data can support a decision immediately or require days of reconstruction. This is particularly relevant for any science-related information, where conclusions must rely on evidence that can be verified, compared and explained. For example, a toxicological result, residue level or compositional value is useful only when its meaning, origin, experimental conditions and reliability are clear.
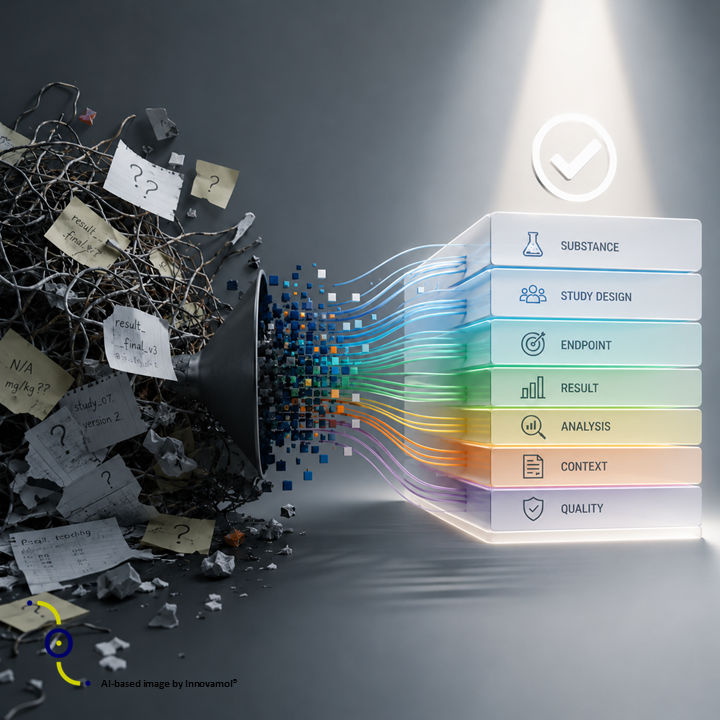
Data-quality problems often emerge during dossier preparation, regulatory review or responses to authority questions. Organisations may hold years of scientific data, yet study codes do not match file names, experimental conditions differ across reports, conversions are undocumented and outdated datasets remain in circulation. The science may be complete, but the assessment slows because the evidence is not decision-ready. The consequences are scientific as well as administrative: poorly defined endpoints can make compatible results appear contradictory, incomplete substance identifiers can cause relevant evidence to be missed, and inadequate method descriptions make comparability difficult to assess. Experts therefore spend time interpreting, converting and validating information before addressing the actual safety question.
Good data quality begins with clarity and traceability. A dataset should show what was measured, where each value originated, which methods and assumptions were used, and which version is authoritative. This reflects ALCOA principles, according to which data should be attributable, legible, contemporaneous, original and accurate. Consistent terminology is equally important because language forms part of the data infrastructure. A substance may be identified by its chemical name, CAS number, active-substance name or product-related identifier, while similar effects may carry different endpoint labels. Controlled terminology makes searches and comparisons more reliable by ensuring that experts are discussing the same concepts, not merely similar words. Documentation should also record how values were extracted, transformed, excluded or recalculated, allowing future users to reconstruct and evaluate the path from raw information to the final dataset.
For regulatory teams, well-described and traceable data make it easier to answer authority questions, identify gaps, update dossiers and reuse previous work. Weak data quality, by contrast, turns every request into a reconstruction exercise. Because correcting inconsistencies at the end of a project is costly, quality should be built in from the start through naming conventions, controlled vocabularies, version control, standard templates and clear documentation rules. For existing datasets, the starting point is a structured review to identify missing information, inconsistent identifiers, undocumented transformations and competing versions, followed by targeted corrections that remain traceable to the original sources. Data quality cannot eliminate uncertainty or replace expert judgement, but it allows experts to focus on interpreting results rather than repairing the surrounding information. This is where Innovamol can help teams working with pesticides, chemicals and novel foods: by organising scientific evidence, harmonising terminology, checking data consistency and documenting how information has been extracted and processed. The aim is to turn fragmented information into traceable datasets that experts can evaluate, update and use to support regulatory decisions.
“Quality is never an accident; it is always the result of intelligent effort” – John Ruskin