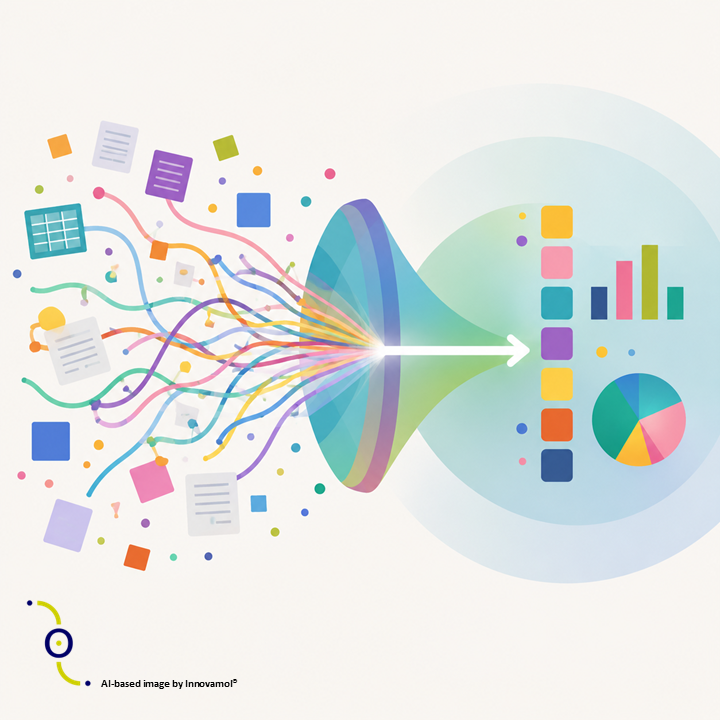
In today’s world, scientific and regulatory decision-making are expected to be faster, more transparent and more robust. At the same time, the evidence behind them is becoming increasingly fragmented. A single question on safety may involve toxicological studies, exposure data, analytical methods, regulatory guidance, historical opinions, literature reviews, environmental data, whole-genome sequencing, nanomaterial size and shape measurements, and estimates of market size and daily intake. Each of these elements can be useful on its own, but when they remain isolated, the overall picture becomes difficult to interpret.
Indeed, this fragmentation of scientific evidence is one of the key challenges of modern regulatory science. The issue is not only the amount of information available, but also the way it is dispersed across different formats, databases, documents and scientific traditions. A study may be stored as a PDF, a dataset as a spreadsheet, and a regulatory conclusion inside a long scientific opinion. As a result, finding the information is only the first step. Even data describing the same parameter may be reported using different formats, units or terminology, making direct comparisons difficult. The real value emerges when fragmented, unstructured information is organised into a structured and harmonized body of evidence, allowing to be connected, compared and understood in context.
This is particularly important in pesticides, GMOs, nanomaterial or other chemicals and novel foods, where regulatory questions are rarely answered by one study alone. Safety assessment depends on weight of evidence, consistency across sources and the ability to trace how data support a conclusion. For instance, a toxicological endpoint may need to be interpreted together with exposure estimates, study reliability, uncertainty factors and regulatory thresholds. When these elements are managed separately, the assessment becomes slower, less transparent and more vulnerable to gaps or misunderstandings. For this reason, evidence integration is becoming as important as data generation. Producing new scientific data remains essential, but their value for regulatory assessment depends on how they are interpreted in context. The FAIR principles, which promote data that are findable, accessible, interoperable and reusable, have helped frame this shift, although they do not, on their own, ensure data harmonisation or comparability. In regulatory science, this means that evidence should not only be stored, but also structured and harmonized in a way that allows it to be understood, compared and reused over time.
Regulatory systems are already moving in this direction. The OECD Harmonised Templates provide standard formats for reporting information on chemicals, human health, environmental effects, uses and exposure. In parallel, IUCLID supports the structured collection and exchange of chemical data across regulatory contexts. More recently, Regulation (EU) 2025/2455, adopted under the One Substance, One Assessment framework, provided for an ECHA-managed Common Data Platform on Chemicals to integrate chemical data across EU regulatory frameworks. These initiatives show that data organisation is not a secondary activity. Rather, it is becoming part of the infrastructure that supports regulatory decision making. However, integration is not simply about putting everything in one place. A large repository can still be difficult to use if the information inside it is not curated, harmonised and connected. True integration requires clear metadata, shared ontologies, controlled vocabularies and traceable links between evidence, interpretation and conclusions. Without this structure, digital systems risk becoming larger versions of the same problem: more information, but not necessarily more clarity.
This is also why AI should be seen as an accelerator, not as a substitute for good data management. AI tools can help search, classify and extract information, but their value depends on the quality of the underlying evidence. If data are inconsistent, poorly labelled or disconnected from context, automation may only reproduce confusion faster. Data overload is often a symptom of fragmented systems rather that an inevitable consequence of scientific progress.The real challenge is to transform fragmented information into structured, reliable and usable knowledge that supports transparent and informed decisions.
At Innovamol, we have been addressing these challenges through projects supporting European regulatory science. Our work focuses on collecting, curating, harmonising and transforming fragmented scientific information into structured datasets that can support analysis and informed decision-making. Some examples of our work include:
| Project | Structured scientific information | Reference |
| Nano-agrochemicals (2024) | Evidence on nano-enabled pesticides, biocides and fertilisers | EUON report and dataset |
| Graphene and 2D materials (2022) | Toxicological and environmental evidence | EUON report |
| Nanomaterials in flame retardants (2026) | Scientific, technical and market evidence | EUON project |
| US FDA toxicity database (2023) | Harmonised non-clinical toxicity data and human safety information for 530 pharmaceuticals | IUCLID database and data visualisation |
| Rat learning and memory (neurotoxicity) (2026) | Structured database of in vivo experimental evidence | Publication forthcoming |
| In vivo genotoxicity (2026) | Consolidated database of experimental genotoxicity studies | Publication forthcoming |
“Without data, you’re just another person with an opinion” – W. Edwards Deming